 Owen Bradley
A PC that reboots without warning is uniquely frustrating because it destroys your work and leaves no explanation. There is no blue screen to read, no error dialog, just a sudden black screen and the startup chime. That instant, silent reset is actually a useful clue in itself: it means something cut power or triggered a hardware protection circuit rather than the operating system deciding to stop. When a PC keeps restarting under load, the cause is almost always in one of three places, power delivery, heat, or memory, and you can isolate which one with a handful of methodical tests. This guide walks through them in the order most likely to find your fault fastest.
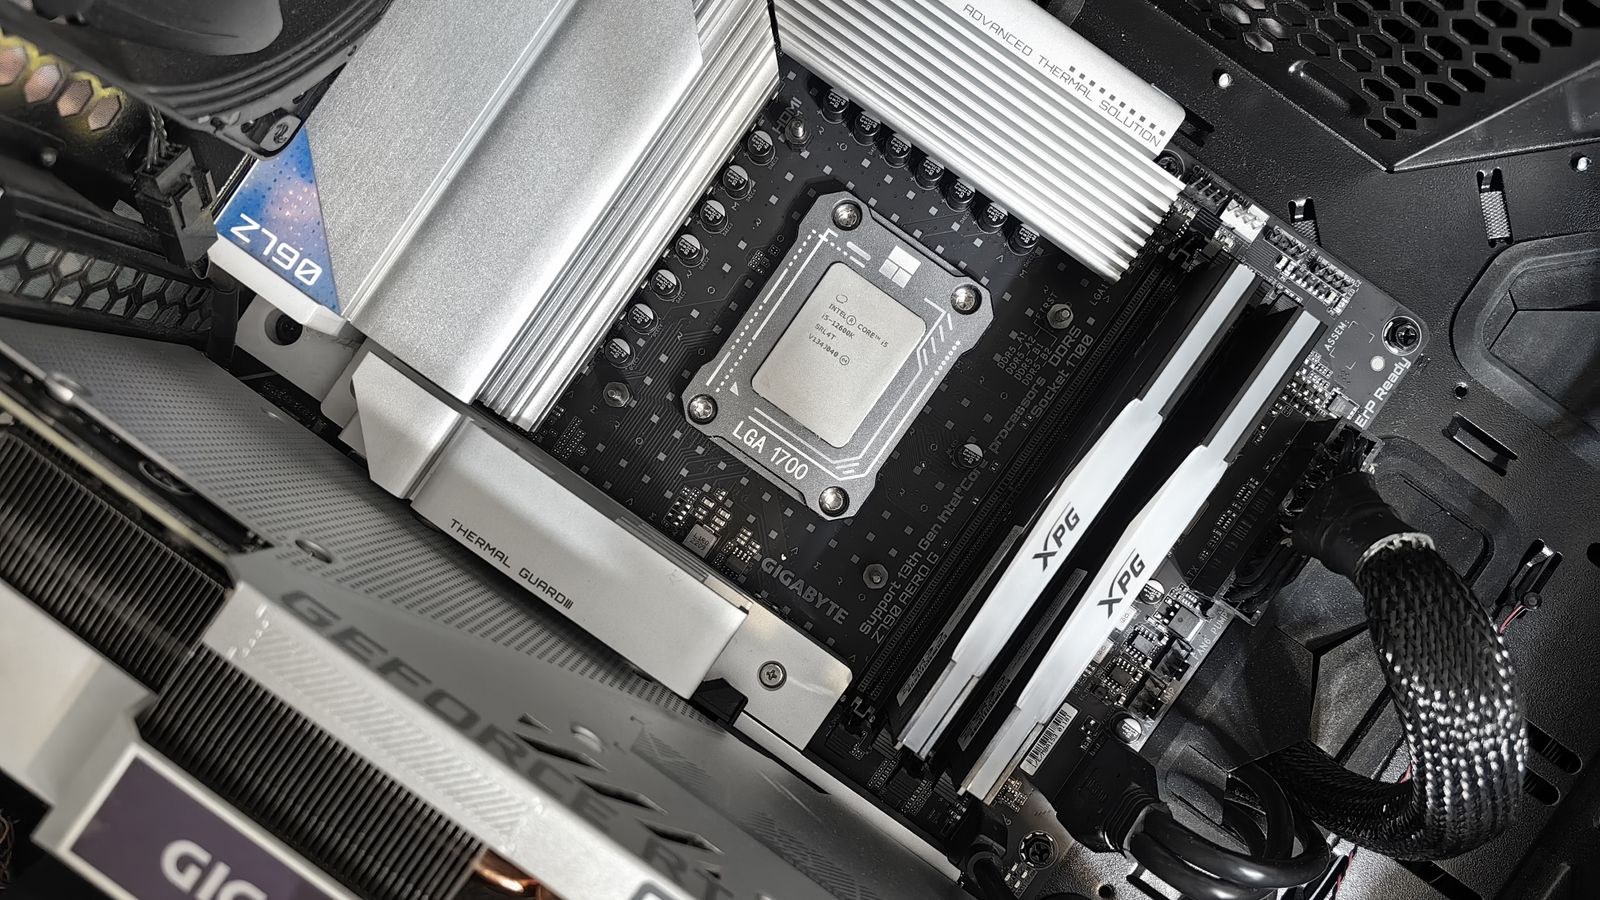
Instant Reset Versus Blue Screen: Why the Difference Matters
If Windows detects a fatal software or driver fault, it stops and displays a stop code before restarting. That path leaves a record. A truly instant reboot with no message means Windows never got the chance, which points at something below the operating system: the power supply dropping out, a thermal or over-current protection tripping, or a hardware fault severe enough to halt the processor outright.
Before assuming the worst, turn off automatic restart so that any blue screens you were missing actually stay on screen. Open System Properties, go to Advanced, then Startup and Recovery Settings, and untick “Automatically restart”. Reboot and carry on as normal. If a stop code now appears, you have a software or driver problem with a name you can research. If the machine still resets instantly with nothing shown, the cause is hardware and the rest of this guide applies.
Check the Event Log for Timing Clues
Open Event Viewer and look under Windows Logs, then System, for Kernel-Power event ID 41. It confirms an unexpected shutdown but does not name the cause. What is useful is the timestamp. Cross-reference it with what you were doing: if every event lands during gaming, rendering, or a benchmark, you have a load-related fault. If they happen at idle or during light browsing, the pattern points more towards memory or a marginal power supply than heat.
Step by Step: Isolating the Cause
- Log the pattern for a day. Note what was running each time it restarts. Load-only, idle-only, and completely random all point in different directions, and this single observation saves hours.
- Rule out the mains supply. Plug the machine directly into a wall socket rather than a strip, and try a different circuit. A shared circuit with a kettle, heater, or power tool on it can dip enough to reset a PC. If restarts coincide with an appliance switching on, that is your answer.
- Monitor temperatures under load. Run a hardware monitoring utility and watch CPU and GPU temperatures while you reproduce the crash. Sustained CPU temperatures at or near 95 to 100 degrees Celsius, or GPU hotspot readings above roughly 110, indicate a cooling problem. A thermal shutdown is usually a hard cut with no warning, exactly matching these symptoms.
- Clean and inspect cooling. Blow dust from heatsink fins, radiators, and filters. Confirm every fan actually spins, including the CPU cooler fan and any pump on a liquid cooler. Thermal paste that has dried out after several years causes exactly this pattern of load-triggered shutdown. If the cooler was never adequate for the processor, upgrading to something from the best CPU coolers for gaming range solves it permanently rather than delaying it.
- Test the memory. Disable your XMP or EXPO profile in BIOS first, since an unstable memory overclock is a leading cause of unexplained resets, and see if the crashes stop. Then run a bootable memory test for at least four passes. Any errors mean a bad module or a profile the controller cannot sustain.
- Reseat every power connector. With the machine unplugged and residual charge drained, unseat and firmly reseat the 24-pin, the CPU 8-pin, and every PCIe cable to the graphics card. Use separate cables to the GPU rather than one daisy-chained lead with two connectors, which is a frequent cause of load-triggered dropouts on high-draw cards.
- Stress the power supply deliberately. Run a CPU stress test and a GPU stress test at the same time for fifteen minutes. That combination pulls peak current and will expose a marginal unit far more reliably than either alone. An immediate reset under combined load is a strong PSU indicator.
- Reduce the load to confirm. Cap your frame rate, lower the power limit on the GPU by twenty percent, or undervolt the CPU slightly. If the restarts stop, you have proved the fault is power or thermal rather than a defective component.
- Swap in a known-good power supply. This is the only conclusive PSU test. If a borrowed unit of adequate capacity ends the problem, replace yours.
- Test with minimal hardware. Remove extra drives, expansion cards, and unnecessary peripherals. A failing drive or a shorting USB device can pull the whole system down.
- Update firmware and chipset drivers, then check for malware. These matter less often than the hardware causes above, but they are quick and occasionally decisive.
Why the Power Supply Is the Usual Suspect
Modern components draw power in short, sharp spikes rather than a smooth line. A graphics card with a nominal 250 watt rating can pull well beyond that for a few milliseconds during a load transient. If the supply cannot ride out those spikes, its over-current or over-power protection trips and cuts everything instantly, which is precisely the symptom you are chasing. This is why a system can run for months and then start rebooting after you install a more demanding game or a new card.
Three things make a supply marginal. The first is inadequate capacity, where the total system draw sits too close to the unit’s rating and leaves no headroom for transients. The second is age, since capacitors degrade and a five to eight year old unit may no longer deliver what its label claims. The third is build quality, because budget units often have poor transient response and weak protection tuning even when the wattage number looks sufficient. Aim for meaningful headroom above your calculated draw rather than the bare minimum; for most current gaming builds an 850 watt class unit is a comfortable target, and the best 850W PSUs comparison covers units with the transient behaviour to match. Efficiency certification is a useful proxy for internal quality, which is why the best 80 Plus Gold PSUs are the sensible default tier, and the broader best PSUs for gaming guide explains how to size one for your specific card.
Heat: What Normal Actually Looks Like
Plenty of people panic at temperatures that are entirely fine. Modern processors are designed to run hot under sustained load, and seeing 80 degrees during a long render is not a fault. What matters is whether the chip is hitting its shutdown threshold. Sustained readings in the mid-nineties with heavy throttling suggest inadequate cooling; a hard reset at that point is the protection circuit doing its job.
The most common physical causes are dust choking a heatsink or radiator, a cooler that was never rated for the processor’s sustained power draw, thermal paste that has dried after several years, a mounting bracket that has loosened, a pump that has failed on a liquid cooler, or a case with so little airflow that intake air is already hot. Check case fan direction too, since a build with more exhaust than intake often runs warmer than a balanced one.
Memory Faults and Why They Cause Silent Resets
Bad memory does not always announce itself with a blue screen. Corruption in the wrong place can halt the processor outright. If your restarts are inconsistent, happening at idle as well as under load, memory deserves early attention. Start by disabling the memory profile, which immediately tells you whether the fault is the modules themselves or an overclock the controller cannot hold, then run a proper test suite.
If a module tests bad, replace the kit rather than a single stick, since matched sets are validated together. Mixing modules from different purchases is itself a common source of instability even when the specifications appear identical, and moving to a single validated kit from the best RAM for gaming selection removes that variable entirely.
Common Mistakes When Chasing Restarts
The biggest is reinstalling Windows first. It takes hours and fixes nothing if the cause is a failing power supply, which it frequently is. Save the reinstall for after hardware has been cleared. The second is changing several things at once, which leaves you with a working machine and no idea why, and no confidence it will stay fixed.
Third is assuming that a PSU wattage number alone guarantees adequacy. A poor 850 watt unit can be less stable under transients than a good 750 watt one. Fourth is ignoring the memory profile, which people leave enabled throughout their entire investigation despite it being a one-click test. Fifth is dismissing the wall socket and power strip, when a shared circuit or a failing extension lead genuinely does cause this. Finally, do not stop testing the moment a change appears to work. Run the machine under heavy load for an hour before declaring it fixed, because intermittent faults love to return the day after you stop watching.
Frequently Asked Questions
Does Kernel-Power event 41 mean my power supply failed?
Not on its own. That event simply records that the system shut down without going through the normal process. It is consistent with a PSU fault, a thermal cut, a memory fault, or even a loose mains cable, so treat it as confirmation of an abrupt reset rather than a diagnosis.
My PC only restarts while gaming. What does that narrow it to?
Load-only restarts point strongly at power delivery or cooling, since those are the conditions that push both to their limits. Test with a frame rate cap or a reduced GPU power limit; if the crashes stop, you have confirmed the category.
Can a failing hard drive cause sudden reboots?
It can, though it is less common than power or memory. A drive drawing abnormal current or a controller fault can destabilise the system. Disconnecting non-essential drives during testing rules it out quickly.
Is it worth reinstalling Windows?
Only after hardware has been eliminated. Instant resets with no stop code are rarely a software problem, and a reinstall costs a lot of time for a low probability of success.
How much power supply headroom should I leave?
Enough that peak system draw sits comfortably below the rating rather than brushing against it. Headroom absorbs transient spikes, keeps the unit in its efficient range, and leaves room for a future graphics card upgrade.
Final Thoughts
Random restarts are a process of elimination, not a guessing game. Turn off automatic restart so any hidden stop codes become visible, note whether the crashes cluster around load or occur at idle, then test in order: mains supply, temperatures, memory profile and modules, power connectors, and finally the power supply under combined CPU and GPU stress. Change one variable at a time and prove each fix with a full hour of heavy load before you trust it. Approach it that way on any build you are troubleshooting in 2026 and you will find the culprit without replacing parts that were never at fault.